Loading project details.
News Crawler
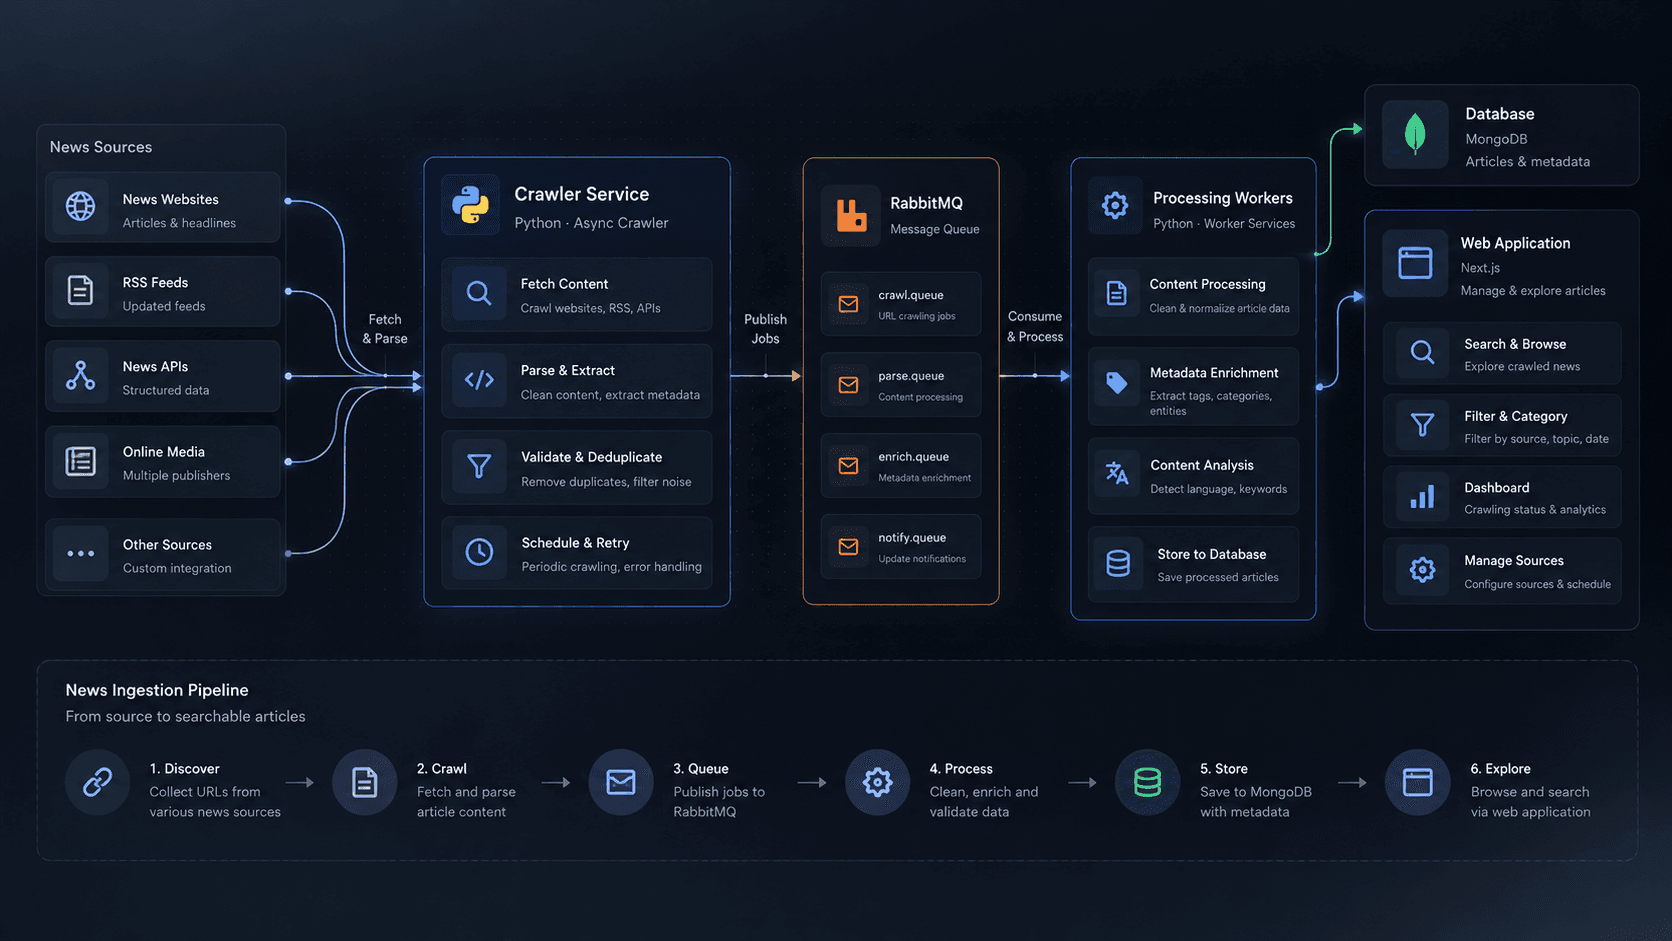
An asynchronous news-ingestion pipeline that uses Python crawlers and RabbitMQ to separate article collection from downstream processing, with MongoDB storage and a Next.js interface.
Context & problem
The system at PT. Spasi Indonesia collects news from external sources and makes the resulting article data available to an internal application. Collection and processing needed to run separately from the web application.
Outcome
Article ingestion runs in the background, independently of the application accessing the collected news.
Engineering decisions
Separate article collection from downstream processing with RabbitMQ. The Python crawler collects article content, extracts relevant data, and produces ingestion jobs. Those jobs pass through the queue for processing before article data and related metadata are stored in MongoDB and accessed through a Next.js interface.
My contribution
Built the Python crawler service, RabbitMQ-backed ingestion, article storage, and frontend integration.
Stored collected article data and related metadata in MongoDB for access through the Next.js application.
Trade-offs
- A message queue adds infrastructure and queue management, but keeps long-running ingestion work out of synchronous application requests.